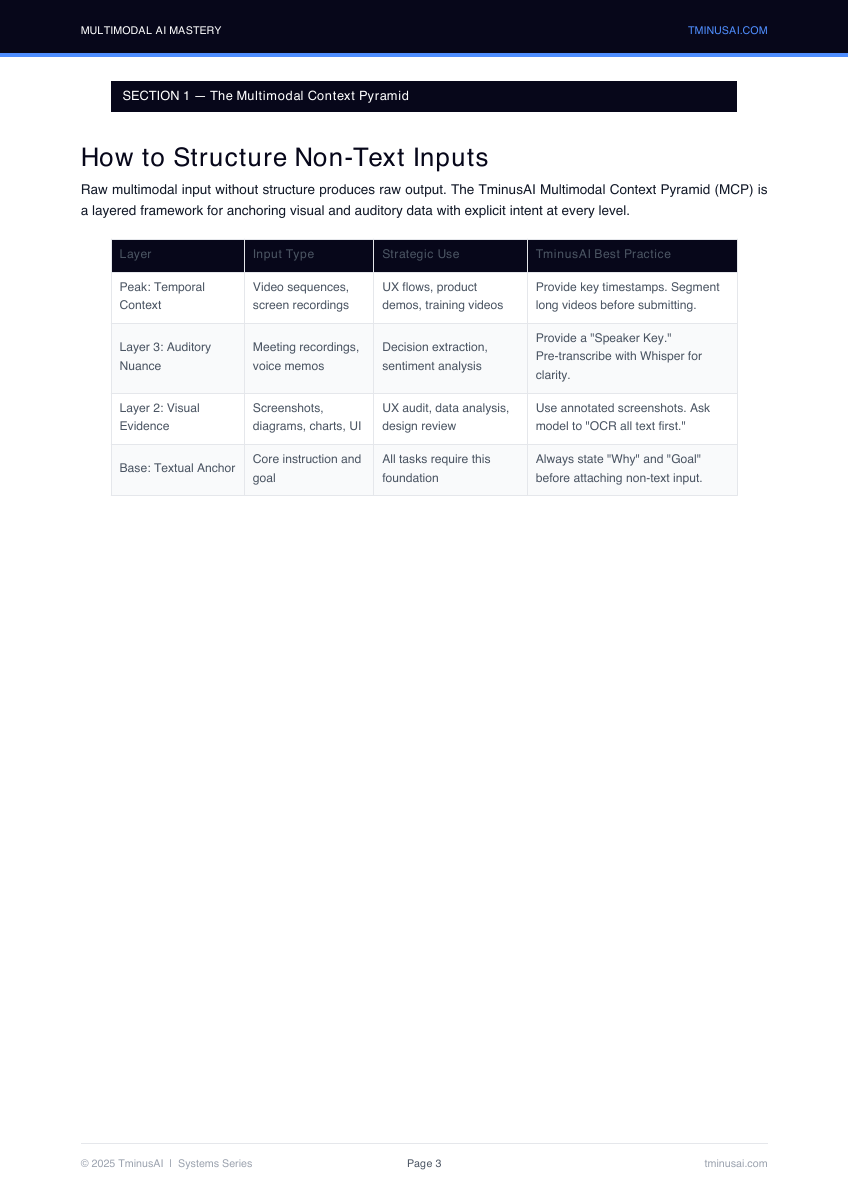
Text-only prompting is no longer the whole game. The strongest AI systems now work across images, audio, video, and documents, but most users still feed them raw inputs with no scaffolding.
This guide gives you the frameworks for structuring non-text context, choosing the right multimodal model, and turning screenshots, recordings, and files into usable business intelligence.
Edition note, checked October 23, 2026: the model comparison in this PDF reflects March 12, 2026 (GPT-5.2, Claude 4 Sonnet, Gemini 2.5 Pro). The current generation is GPT-6 at OpenAI, Claude Fable 5.1, Opus 5.5, Sonnet 5.5, and Haiku 5.5 at Anthropic, and Gemini 4 Argon at Google, which limited Gemini 2.5 API access to existing users on September 18, 2026. The frameworks for structuring images, audio, video, and documents do not depend on those model names.
Subscribe To
The Systems Dispatch
Weekly AI systems notes, guide drops, and practical workflows built for serious operators.